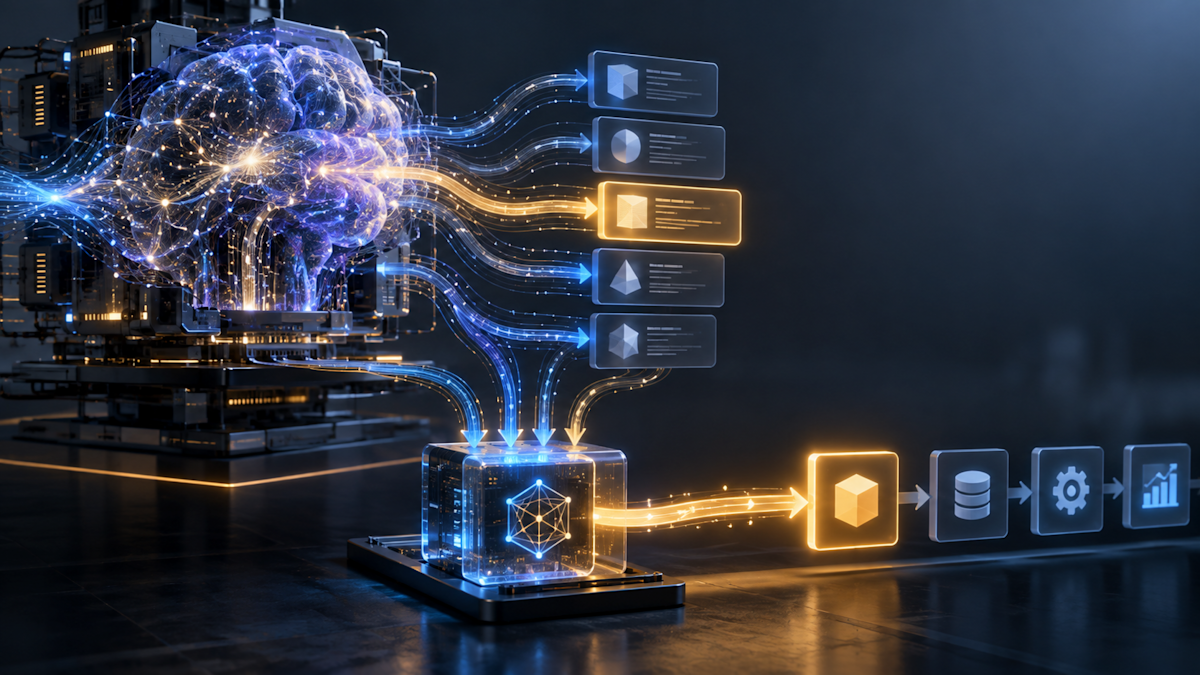
Stanford and Nvidia's open CLM-8B caches reusable agent actions and runs up to 9x faster than Jev in tests AI agents often use LLMs to choose between a fixed set of tools or rank candidate outputs. In each case, the model processes a prompt and generates tokens even though the application only needs a bounded decision. Read more